







Benchmarks that check what an agent actually committed, agents whose every decision is inspectable,
and the data plumbing underneath. Founder of Thrill AI · MS in Data Science, George Mason '25.


21 merged pull requests across 10 repositories, plus 8 more under review in projects such as marimo, beets and Sphinx.
| Project | Stars | Merged work |
|---|---|---|
| roboflow/supervision | 51k | 4 PRs. Mean average recall excludes crowd and ignored targets, oriented-box IoU is thresholded in float32 like box IoU, Pascal VOC export rounds box corners instead of truncating, and the resize fallback matches OpenCV's nearest-neighbour grid |
| sqlfluff/sqlfluff | 10k | Honour inline dialect directives when loading SQL files |
| MrLesk/Backlog.md | 7.1k | Skip the fetch when the requested Git remote is absent |
| PasarGuard/panel | 2.8k | Copy links from menus on insecure contexts |
| pydantic/httpx2 | 1.6k | Contributing docs point at the discussion categories that exist |
| libredb/libredb-studio | 1.3k | 8 PRs, listed in CONTRIBUTORS. Built the one-command Keycloak SSO demo stack, fixed MySQL schema diffs emitting unquoted column defaults, bound the demo stacks to loopback (#960, #1004) and four docs fixes |
| roboflow/roboflow-python | 636 | Ruff 0.17 ICN001 compliance for datetime imports |
Under review: marimo (23k) · beets (15.8k) · roboflow/notebooks (9.7k) · Sphinx (8.1k) · tunarr (2.7k) · NVIDIA NeMo Curator (1.8k) · narwhals (1.7k)
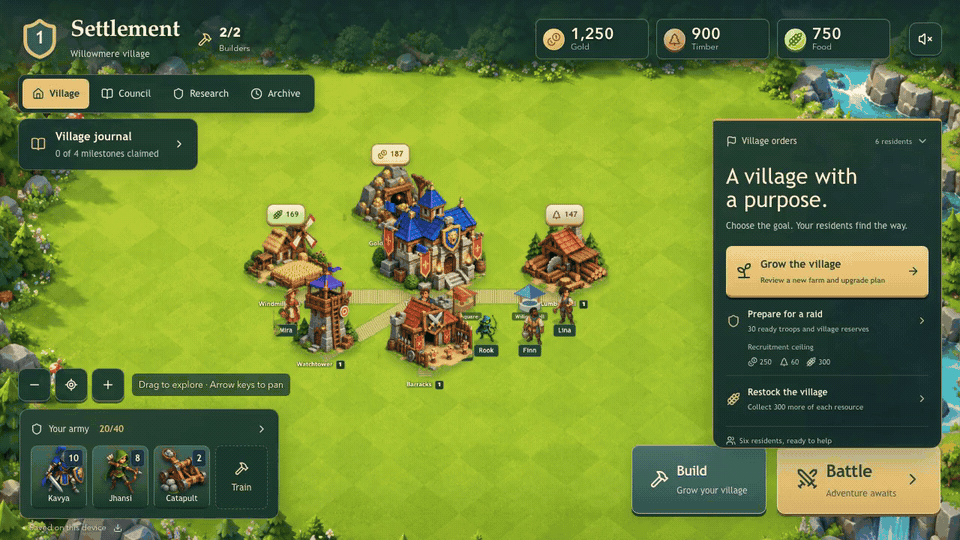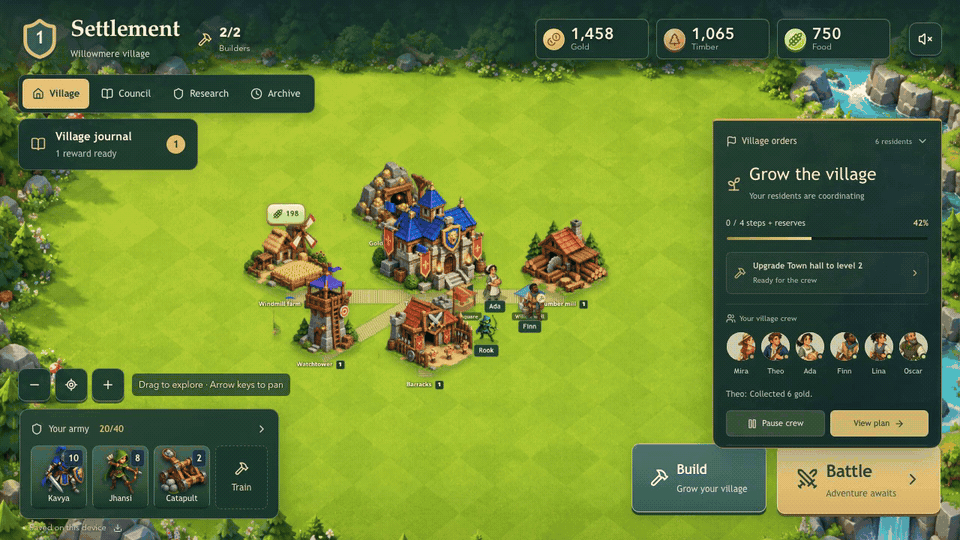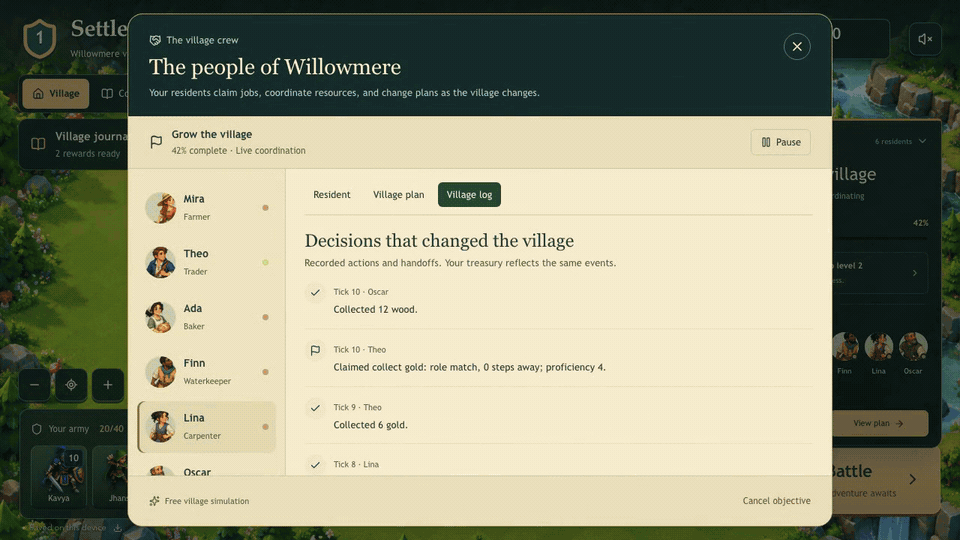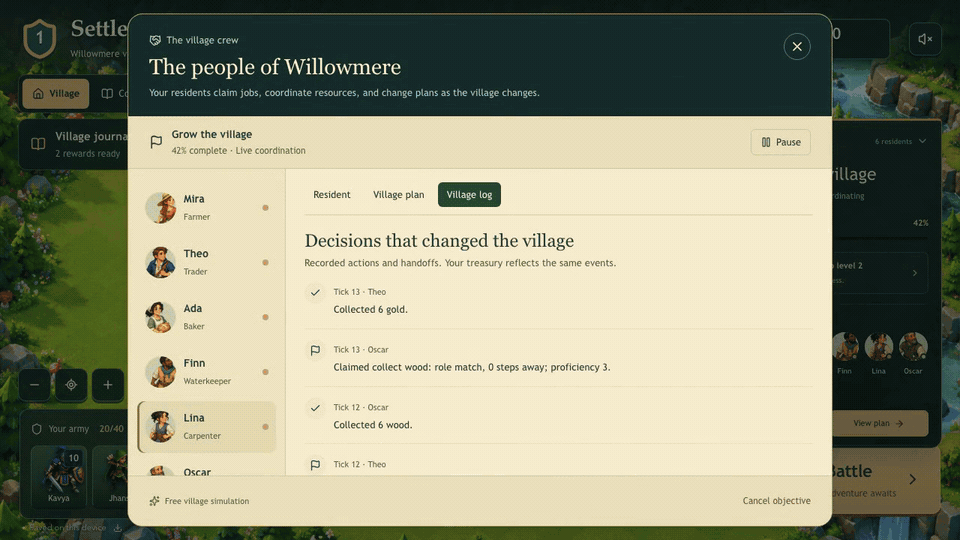
Settlement: a multi-agent simulation with an inspectable decision trail
Six residents bid for jobs, gather, build and recruit toward one objective you set. Open any of them to see the decision, the route and the memory behind it. It doubles as a testbed: point npx settlement-testbed at your own agent's HTTP endpoint and get a report anyone can re-verify.


IndicOrderBench: a benchmark for voice-ordering agents
A voice agent can read back "one paneer wrap, no onion" and still commit two wraps with onion. IndicOrderBench scores the order that actually reached the backend, in English and Hinglish, with a CI exit code. No judge model, and the demo needs no API keys.

uvx --from indicorderbench iob demo --out demo-out
aegis-shred: crypto-shredding for user data erasure
Crypto-shredding for application data: each user gets their own encryption key, so erasing a person makes every copy of their data unreadable, backups included. Rust core, Python package, aegis CLI. Alpha, not yet independently audited.

| release-lens | Shows exactly what changed between two npm tarballs (byte growth, file hashes, manifest changes) without installing either one. Browser app and npm CLI |
| aegiseval | Red-teaming a tool-using RAG agent: threat model, 260-prompt golden set, validated LLM judge, mitigations measured before and after |
| MerchantLens | Databricks lakehouse where access rules are enforced by the query engine rather than by the agent |
| Village Sentinel | Governance agent that routes each decision through a small Decider model, checks evidence when uncertain and escalates to Amazon Bedrock only when needed. Live demo |
| mcp-rust-sdk | Rust SDK for building Model Context Protocol servers |
| rocm-devops-starter | Probe, smoke-test training run, container and CI for PyTorch on AMD GPUs, with a record of exactly what ran on real hardware |
Core stack: Python · TypeScript · Rust · SQL · FastAPI · Next.js · LangGraph · MCP · Databricks · Postgres · Docker · GitHub Actions
Current focus: contributing to Roboflow's computer-vision libraries, bringing IndicOrderBench and aegis-shred to their first external users, and publishing measured ordering accuracy for real LLM voice stacks.
Open to AI/ML engineering (including computer vision), data engineering and data analyst roles.