



Applied AI engineer. I build LLM applications and measure whether they're right.
I build LLM systems you can check: answers that show their working, trace back to a source, and admit when there isn't one. I score them against a benchmark instead of trusting a demo. Python and TypeScript day to day, Rust when something has to be fast and local, Linux throughout.
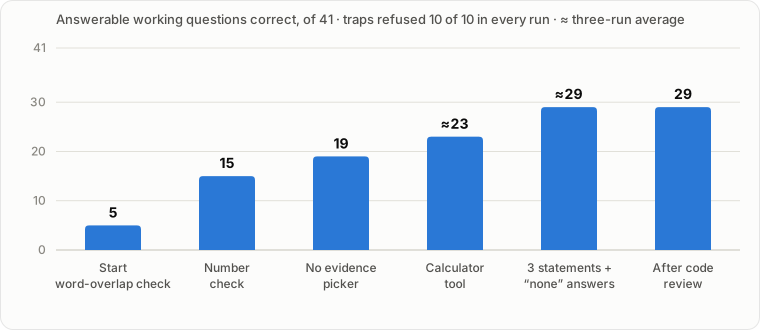
Ask a company's 10-K a question and get an answer you can check. Calculations go through a calculator instead of the model, every number in the answer is checked against the filing, and anything it can't back up becomes "not in the document".
On a held-out set of 34 questions, run once, it answered 21 of 26 answerable questions correctly and refused 8 of 8 that the filing doesn't answer.
Show your coding agent the problem instead of typing it out. Hit a hotkey, talk, and draw on your screen. One Ctrl+V pastes timestamped notes and an annotated contact sheet into Claude Code, Codex, or any chat box. It's a GNOME Shell extension with a Rust service behind it, and transcription runs locally with whisper.cpp. It installs with one command and ships as versioned releases.

Merged a fix to bulwark-mcp, a proxy that catches prompt injection before it reaches your AI agent: it now explains what's wrong when Ollama isn't running instead of failing opaquely.


Retrieval and evals · tool calling · Supabase · GitHub Actions · Vercel